Medical image-to-text generation with visual grounding
Oct 5, 2026
·
1 min read
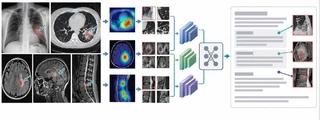 Overview of the thesis topic
The problem
Development and validation of a model that generates structured reports from medical images while grounding statements in image regions or visual evidence.
What you will do
As in every MSc thesis in the BEAR group, you will:
- develop a novel module, neural architecture or learning strategy that addresses an open challenge in medical imaging (not a plain replication of existing methods);
- validate it in one or more clinically relevant application domains, on established medical imaging benchmarks.
Possible application domains
Radiology (miscellaneous) · Neuro-radiology · Neuro-oncology · Ophthalmology
Example to follow
Modality-Aware Token Interaction (MATI): a module that structures multimodal interaction within a single token stream by partitioning the embedding space into modality-aligned subspaces, integrated into a neural backbone (e.g. UNETR) and validated on an established benchmark (e.g. BraTS for multimodal brain tumour segmentation), with optional generalisation to more backbones and benchmarks.